


Analog vs Digital vs Hybrid: 5 Surprisingly Effective Systems for Remembering Everything (Without Feeling Like a Robot)
Why “remembering everything” feels harder now
Between Slack pings, appointment reminders, group chats, and that one idea you swear you’ll write down “later,” modern life isn’t short on information—it’s short on reliable retrieval. The real problem isn’t memory; it’s having a system you actually use when you’re busy, tired, or distracted.
This article compares five practical, real-world systems for capturing and recalling tasks, notes, and ideas. Some are analog, some are fully digital, and some are “best of both.” The goal: pick a setup that matches your brain and your schedule, not someone else’s productivity aesthetic.
We’ll evaluate each option by:
- Friction: how hard it is to use consistently
- Searchability: how fast you can retrieve what you need
- Reliability: how well it survives chaos (dead batteries, travel, interruptions)
- Maintenance: how much weekly “system work” it demands
Option 1: The “One Notebook” Capture System (Analog Minimalist)
How it works
You keep a single notebook and write everything in it: meeting notes, to-dos, random ideas, grocery lists. The rule is simple: if it matters, it goes in the notebook. No sticky notes, no loose scraps.
Best for
- People who remember better when they write by hand
- Anyone who hates app switching and digital clutter
- Students, creatives, and folks in meetings all day
Pros
- Low friction: open notebook, write
- Reliable: no logins, no syncing
- Better retention: many people recall handwritten notes more easily than typed ones
Cons
- Low searchability: finding an old detail can feel like archaeology
- Hard to share: collaboration is awkward
- Single point of failure: lose the notebook, lose the archive
Actionable tips to make it actually work
- Use an index on the first 2 pages: whenever you start a new topic (Project X, “Car stuff,” “Health”), add the page number.
- Mark tasks with a symbol: for example, “□” for a to-do and “★” for something to remember.
- Do a 3-minute daily sweep: at the end of the day, scan today’s page and rewrite only the still-relevant tasks onto tomorrow’s page.
Option 2: The Phone-First Stack (Notes App + Reminders + Voice)
How it works
This is the “I’m already on my phone” approach. You capture quick notes in your default notes app, tasks in a reminders/to-do app, and use voice dictation when typing is too slow. Everything lives in your pocket.
Best for
- Busy parents, commuters, and anyone often away from a desk
- People who need search and fast capture
- Folks who already live in their calendar
Pros
- Fast capture anywhere: especially with widgets and voice
- High searchability: keywords, tags, and filters
- Easy reminders: location/time-based nudges are powerful
Cons
- Distraction risk: you open your phone to write a task and suddenly you’re reading a thread about air fryers
- System sprawl: notes in three places, tasks in two, and now nothing feels trustworthy
- Notification fatigue: reminders stop working when you learn to ignore them
Actionable tips
- Create one “Inbox” note: everything goes there first; sort it later.
- Use two task lists max: “Today” and “Not Today.” If an app forces more, ignore them.
- Turn off non-essential notifications: keep only calendar + time-critical reminders.
Option 3: The Weekly “Personal Ops” Board (Kanban for Real Life)
How it works
Instead of a long to-do list, you organize tasks on a simple board with columns like “To Do,” “Doing,” and “Done.” You can do this on a whiteboard, sticky notes, or a digital board. The magic is limiting what’s in “Doing.”
Best for
- People who feel overwhelmed by endless lists
- Anyone juggling multiple projects (home, work, side hustle)
- Visual thinkers who like seeing progress
Pros
- Clarity: you see what you’ve committed to
- Momentum: “Done” is motivating
- Prevents overload: the board makes overcommitting obvious
Cons
- Setup time: you need an initial brain dump
- Maintenance: a messy board becomes noise
- Not great for tiny quick tasks: you might spend longer managing cards than doing the thing
Real-world example
If you’re planning a move, a Kanban board can split “Call utilities,” “Pack kitchen,” and “Change address” into bite-sized cards. Put only 3 cards in “Doing” at a time. You’ll feel slower for one day—and then you’ll feel way faster for the next two weeks.
Actionable tips
- Cap “Doing” at 3: this is the whole point.
- Add a “Waiting on” column: for tasks blocked by other people.
- Do a 15-minute weekly reset: archive old cards and pick the next week’s focus.
Option 4: The “Second Brain Lite” (PARA Without the Pain)
How it works
PARA stands for Projects, Areas, Resources, Archive. In full form, it can feel like a lifestyle. “Second Brain Lite” keeps the structure but dials down the complexity. You store notes and documents in four buckets so you can find them later.
Best for
- People who manage lots of information (research, content, client work)
- Anyone tired of losing links, files, and reference notes
- Folks who want long-term organization, not just daily task tracking
Pros
- Excellent retrieval: information doesn’t vanish after a week
- Scales well: works for a single project or 50
- Reduces mental load: fewer “where did I put that?” moments
Cons
- Initial sorting: you’ll spend time cleaning up the mess
- Temptation to over-organize: folders can become procrastination
Actionable tips
- Keep “Projects” short: if it doesn’t have a deadline or clear outcome, it’s not a project.
- Use “Areas” for ongoing responsibilities: Health, Finances, Household, Career.
- Schedule a monthly archive day: move completed projects out so your system stays light.
Option 5: The Hybrid “Paper + Digital Anchor” System (Most Practical for Most People)
How it works
You use paper for daily thinking and prioritization, and digital tools as the long-term anchor. In practice, this looks like:
- A small notebook or daily planner for today’s plan and quick notes
- A calendar app as the source of truth for time commitments
- A digital notes app (or folder) for anything you may need to search later
Best for
- People who like writing but also need search
- Anyone who wants a system resilient to distractions
- Folks balancing personal life + work projects
Pros
- Low friction day-to-day: paper keeps you focused
- Strong retrieval: digital keeps reference material searchable
- Fails gracefully: if your phone dies, your day plan still exists
Cons
- Requires a bridge habit: you must transfer key items from paper to digital
- Two places to look: unless you define clear rules
A simple bridge habit that takes 5 minutes
- End-of-day scan: circle anything on paper that must live longer than 24 hours.
- Transfer: tasks go to your reminders/to-do list; reference notes go to your digital notes under a clear title.
- Snap a photo: if you’re rushed, take a photo of the page and upload it to your notes app. Sort later.
What the data says about attention (and why your system should be simple)
Attention is a limited resource, and the modern info environment is not exactly designed to protect it. If you want a quick pulse on how tech, business, and policy changes are shaping daily life (including the way we consume information), browsing a trusted newsroom can help you calibrate your habits. For example, Reuters reporting on technology and society frequently covers how platforms, devices, and workplace tools evolve—useful context when you’re deciding how much complexity your personal system should include.
Practical takeaway: if your setup requires constant fiddling, it will collapse the moment life gets busy. Choose a system that still works on your worst Tuesday, not your best Sunday.
Quick comparison: which system should you pick?
If you want the simplest thing that works
Pick Option 1 (One Notebook). Add an index and a daily sweep and you’ll be shocked how far it takes you.
If you’re always on the move and need search
Pick Option 2 (Phone-First), but enforce an “Inbox note” and keep task lists minimal.
If you’re overwhelmed and need visual control
Pick Option 3 (Personal Ops Kanban) and cap “Doing” at 3.
If you manage lots of info and hate losing links/files
Pick Option 4 (Second Brain Lite) and archive monthly.
If you want the best all-around setup
Pick Option 5 (Hybrid Paper + Digital Anchor). It’s the sweet spot for focus and retrieval.
Conclusion: build for retrieval, not perfection
The best memory system isn’t the one with the prettiest templates or the most features—it’s the one you trust enough to use every day. Start with the approach that feels easiest, then add exactly one improvement at a time (indexing, a weekly reset, or a transfer habit). Within a month, you’ll spend less time trying to remember what you forgot—and more time doing the stuff that actually matters.
If you’re not sure where to begin, choose the Hybrid Paper + Digital Anchor system and run it for two weeks. You’ll learn your preferences fast, and you can tweak from there without burning the whole thing down.
9 Data Services Tactics to Turn Satellite & Sensor Data Into Decision-Ready Insights (Without Drowning in Files)
Why “Earth data” is suddenly everyone’s data problem
Data services teams are increasingly being asked to operationalize “Earth data” — information captured from satellites, drones, in-field sensors, smartphones, and public datasets — to support decisions in insurance, utilities, construction, agriculture, climate risk, and even retail. The opportunity is huge, but so are the obstacles: massive files, inconsistent metadata, uncertain quality, and the gap between analytics output and business action.
This article focuses on a specific, evergreen challenge: how to convert geospatial and sensor data into decision-ready products (dashboards, alerts, risk scores, workflow triggers) rather than a messy archive of imagery and time series. Below are nine practical tactics your data services organization can apply immediately — regardless of whether you’re building for internal stakeholders or selling data products externally.
9 Practical Data Services Tactics for Decision-Ready Satellite & Sensor Insights
1) Start with “decision latency” and work backward
Most teams begin by asking, “What data do we have?” A better starting point is: How fast does the business need to act? Decision latency (minutes, hours, days, or months) should drive your architecture, refresh rate, and even whether you need streaming data at all.
- Example: A utility monitoring vegetation near power lines may need weekly change detection for planning, but near-real-time alerts for storm response.
- Actionable tip: Document the required “time-to-action” for each use case (e.g., flood response alerts: <2 hours; roof condition underwriting: quarterly). Use that to set SLAs for ingestion, processing, and delivery.
When latency is explicit, it becomes easier to justify cost tradeoffs (e.g., paying for rapid revisit imagery vs. using free but delayed sources).
2) Treat metadata like a first-class product (not a sidecar)
Earth observation and sensor data is only useful if it is searchable, comparable, and explainable. Metadata is what turns “files” into “assets.”
- What to capture: spatial extent, resolution, capture time, sensor type, processing level, cloud cover, known gaps, coordinate reference system, and lineage (how it was transformed).
- Actionable tip: Implement a metadata standard and enforce it at ingestion. Even a lightweight internal schema (plus automated checks) prevents downstream confusion.
In practice, a robust metadata layer is often the difference between a usable data catalog and an expensive storage bill.
3) Design “analysis-ready” pipelines so analysts don’t reinvent prep work
Many geospatial initiatives stall because every project starts with the same cleaning steps: reprojection, tiling, cloud masking, gap filling, time alignment, and unit conversion. “Analysis-ready data” (ARD) formalizes and automates these steps.
- Real-world example: For crop monitoring, teams frequently standardize vegetation indices (like NDVI) across time and sensor types, ensuring consistent resolution and coordinate systems so trends are meaningful.
- Actionable tip: Create reusable pipeline components (e.g., “cloud mask + tile + normalize”) and version them like software. Publish them as internal services so every project uses the same definitions.
This improves consistency, reduces cycle time, and helps stakeholders trust results because the same transformations are applied every time.
4) Use “small data” derivatives to avoid moving massive rasters
One common failure mode in Earth data programs is trying to deliver raw imagery to everyone. It’s slow, expensive, and rarely necessary for decision-making. Instead, generate compact derivatives tailored to business questions.
- Examples of derivatives: parcel-level risk scores, building footprints with damage probability, road passability classifications, heat maps aggregated to neighborhood blocks, or time-series features (weekly mean, anomaly flags).
- Actionable tip: For each user group, define the smallest “decision unit” (e.g., address, asset ID, grid cell, field boundary). Store and serve data at that unit.
This is a data services superpower: turning terabytes of raster data into kilobytes of actionable features that plug into CRMs, ticketing systems, or underwriting tools.
5) Implement uncertainty and quality scoring as part of the deliverable
In Earth observation and sensor analytics, uncertainty is unavoidable: clouds obscure imagery, sensors drift, and models generalize imperfectly. Teams build trust faster when they quantify quality and communicate it clearly.
- What “quality” can mean: percentage of cloud-free pixels, sensor uptime, temporal gaps, model confidence, or validation error metrics.
- Actionable tip: Ship a “quality field” alongside every metric (e.g., risk_score plus risk_score_confidence). Then define business rules: when confidence is low, route for manual review instead of auto-action.
For instance, an insurer can automatically flag properties for inspection only when the confidence is high, reducing wasted field visits.
6) Align data products to workflows (alerts, tickets, and approvals)
Dashboards are useful, but they often fail to change outcomes because they depend on someone remembering to check them. Decision-ready data services integrate with workflows people already use.
- Examples: push flood alerts into incident management tools, create maintenance tickets when vegetation risk exceeds a threshold, or trigger re-inspections when roof degradation accelerates.
- Actionable tip: Define “last mile” integrations early. If end users live in ServiceNow, Salesforce, or a custom asset management system, plan an API or event-based delivery route from day one.
As a simple rule: if a data insight doesn’t create a task, notification, or decision checkpoint, it’s likely to be ignored.
7) Validate models with “ground truth” partnerships (and document lineage)
Trending analytics like damage detection, shoreline change classification, and illegal land-use identification can be powerful — but only if validated against real-world observations. Data services teams should plan validation like a product requirement, not a research afterthought.
- Ground truth sources: field inspections, mobile app surveys, drone spot checks, customer claims data, or third-party audits.
- Actionable tip: Maintain a validation dataset that is independent from training data and track performance by geography and season. Model accuracy can drift due to changing conditions, new construction, or climate-related shifts.
When communicating results to non-technical stakeholders, pair metrics with clear lineage: what data sources were used, what transformations occurred, and what the known limitations are.
8) Blend public context data to boost interpretability (not just accuracy)
Earth data gains meaning when you add context: land cover, elevation, weather, hydrology, infrastructure networks, and demographic boundaries. Even when context layers don’t dramatically improve model accuracy, they often improve interpretability — helping decision-makers understand “why.”
- Real-world example: A flood risk signal becomes more actionable when combined with elevation, distance-to-water, and recent rainfall totals, allowing operations teams to prioritize vulnerable assets.
- Authority reference: For broader environmental context and science storytelling that helps stakeholders understand the “why” behind geospatial shifts, refer to resources from National Geographic’s environmental coverage.
- Actionable tip: Build a “context layer library” and standardize join keys (geohash/grid IDs, parcel IDs, asset IDs). This prevents every project from redoing spatial joins in ad hoc ways.
Interpretability is often the difference between an insight that’s debated and an insight that’s acted upon.
9) Price and govern Earth-data products by “usage outcomes,” not storage or scenes
If your organization provides data services to other teams (or externally), a common trap is pricing and governance around the wrong units: gigabytes stored, number of scenes, or raw API calls. Those measures don’t map well to value.
- Better units: number of assets monitored, number of validated alerts delivered, number of workflows automated, or reduction in time-to-insight.
- Actionable tip: Create a simple product contract: what decisions are supported, what refresh rate is guaranteed, what “quality thresholds” apply, and what actions are expected when confidence is high vs. low.
This outcome-based approach also helps with governance: you can apply stricter controls where automated actions carry higher risk (e.g., compliance, safety) and lighter controls where insights are advisory.
Conclusion: Make Earth data operational, not ornamental
Satellite imagery and sensor feeds can easily become a “cool data lake” that impresses in demos but fails in day-to-day operations. The data services teams that win are the ones that engineer for decisions: they define latency, standardize metadata, create analysis-ready pipelines, produce small actionable derivatives, communicate uncertainty, integrate with workflows, validate with ground truth, enrich with contextual layers, and govern by outcomes.
If you’re building or modernizing a geospatial data capability, pick two tactics from this list and implement them end-to-end in a single use case. The compound effect of repeatable pipelines and workflow integration is what turns Earth data into a reliable decision engine.
UAS Lidar vs Mobile Mapping vs SLAM Scanners: Which Reality-Capture Workflow Wins for Construction Surveying in 2026?
Reality capture is now a schedule tool, not just a survey deliverable
Construction teams are under constant pressure to cut rework, verify quantities faster, and document progress defensibly. The biggest shift in the last few years is that “reality capture” has moved from a specialist add-on to a core production workflow that ties directly to pay applications, claims support, and weekly planning. For survey managers, the real question isn’t “Should we scan?”—it’s which capture approach (or mix) fits your site constraints, accuracy requirements, staffing, and downstream CAD/BIM needs.
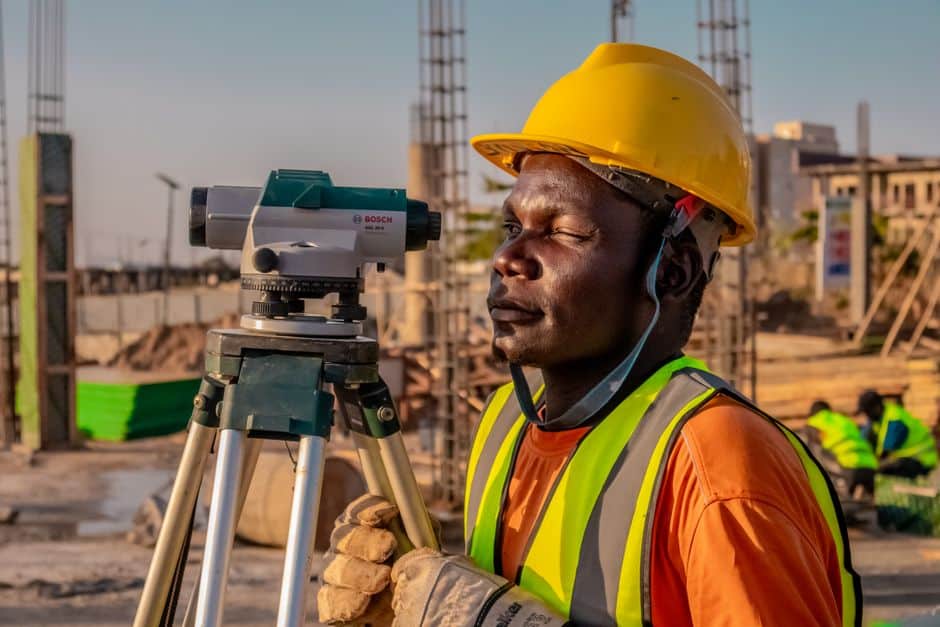
This comparison breaks down three of the most used (and often misunderstood) approaches for construction surveying today: UAS lidar (drone-based), vehicle-based mobile mapping, and handheld/backpack SLAM scanners. You’ll get practical selection criteria, realistic performance expectations, and specific use cases where each method tends to outperform the others.
The three contenders (and what they’re truly best at)
1) UAS lidar (drone lidar)
What it is: A lidar sensor mounted to a drone collects point clouds from above. It’s typically paired with GNSS/IMU for trajectory and often tied to ground control points (GCPs) or check points for QA.
Where it shines: Rapid coverage of large sites, earthworks, stockpiles, corridors, and areas with limited ground access. Also useful where vegetation filtering matters (e.g., preconstruction topo through brush).
2) Vehicle-based mobile mapping (mobile lidar)
What it is: Lidar and imagery sensors mounted to a vehicle, collecting dense data along drivable paths. Uses GNSS/IMU with additional constraints (e.g., wheel odometry) depending on the system.
Where it shines: Linear infrastructure, paved corridors, roadway/bridge work zones, and projects needing consistent capture of lane lines, curb returns, and roadside assets at speed.
3) SLAM scanners (handheld/backpack/push-cart)
What it is: Simultaneous Localization and Mapping (SLAM) sensors—often lidar-based—map environments by recognizing geometric features and tracking motion. Many support control-based alignment to tighten global accuracy.
Where it shines: Interiors, MEP spaces, congested structures, partially built floors, as-builts in areas where GNSS is blocked, and rapid capture of “messy” environments with frequent occlusions.
Comparison: performance, risk, and the real cost per deliverable
Accuracy and repeatability (how tight is “tight enough”?)
Accuracy is where marketing claims and construction tolerance requirements often clash. The right way to compare systems is to separate:
- Relative accuracy (how well features relate to each other within the scan)
- Absolute accuracy (how well the dataset fits your project control and design coordinate system)
UAS lidar: Often strong on absolute accuracy when properly controlled, but performance is sensitive to trajectory quality, GNSS conditions, and control layout. Expect better outcomes when you maintain consistent flight parameters, fly crosshatch in critical zones, and use check points separate from control.
Mobile mapping: Can be highly repeatable along corridors, but suffers in “GNSS-challenged” areas (urban canyons, under structures, tree canopies). If your project involves repeated runs for progress monitoring, consistent route planning and robust QA (loop closures, check shots) matter as much as sensor specs.
SLAM scanners: Excellent relative accuracy for interiors and short loops, but absolute accuracy depends heavily on control integration. If you need a scan to drive layout or verify embed locations, a control-based workflow (targets, traverses, or known points) is non-negotiable.
Actionable tip: Decide your acceptance criteria before you mobilize. For example, if you need ±0.03 ft (±10 mm) at critical anchor bolts, don’t rely on an uncontrolled SLAM walk. Conversely, if your goal is “progress volumes within 2–3%,” UAS lidar may be more than sufficient—and faster.
Speed and coverage (what can you capture per shift?)
UAS lidar: High area coverage per hour. The time sink is often not the flight—it’s planning, permitting, safety coordination, and processing/QA. For active sites, coordinate with the superintendent to avoid tower crane swing zones, blasting windows, or high-dust operations that can degrade returns.
Mobile mapping: Extremely fast for drivable coverage; a few passes can capture miles of corridor. But you may need traffic control, spotters, and a schedule window that doesn’t conflict with paving operations or haul routes.
SLAM scanners: Fastest “time-to-capture” indoors. A skilled operator can scan a floor in minutes. The tradeoff is drift risk if you do long, feature-poor runs (blank corridors, repetitive geometry) without loop closures or control.
Safety and access (the hidden driver)
Reality capture choices increasingly come down to safety constraints:
- UAS lidar keeps staff out of haul roads, unstable slopes, and stockpiles—major risk reduction.
- Mobile mapping reduces time on foot in traffic-exposed corridors but introduces vehicle operation and work-zone safety requirements.
- SLAM scanning is ideal when areas are physically accessible but GNSS is unavailable—think basements, mechanical rooms, or retrofit spaces.
Data usefulness: design-to-field, pay apps, and claims
Point clouds are only valuable if they support decisions. In 2026, many project teams are using capture outputs for:
- Earthwork quantities (cut/fill, stockpiles)
- Progress verification (percent complete by zone)
- As-built documentation (MEP routing, structural steel, slab openings)
- Dispute support (what existed on a given date)
For economic context, construction cost volatility and labor constraints continue to push teams toward productivity tech and defensible documentation. For broader reporting on construction markets and cost pressures, project leaders often track major industry updates through sources like Reuters construction and infrastructure coverage.
Where each workflow wins: specific construction scenarios
Scenario A: Weekly earthwork quantities on a 200-acre industrial site
Best fit: UAS lidar
- Why: Fast site-wide coverage, fewer boots in high-risk grading areas, consistent surface models for week-over-week comparisons.
- Pro move: Set permanent check points outside disturbance zones. Use the same flight plan and classification rules each week to avoid “process drift” that looks like real volume change.
- Deliverable tip: Provide a change map (surface-to-surface) plus a short QA summary (control, RMSE, check residuals). Owners care about defensibility as much as numbers.
Scenario B: Highway widening with multiple interchanges and night shifts
Best fit: Vehicle-based mobile mapping (with selective static scans at pinch points)
- Why: Corridor efficiency is unmatched; you can capture assets, pavement edges, barrier, signage, and tie-ins quickly during closures.
- Pro move: Plan repeatable routes and run calibration checks at the start of each shift. If GNSS is compromised under bridges, add short static occupations or control-target tie-ins near structures.
- Deliverable tip: Extract linework that field crews actually use: edges of pavement, joint lines, barrier faces. Don’t hand over an unstructured point cloud and call it done.
Scenario C: As-built verification in a dense hospital MEP retrofit
Best fit: SLAM scanning (control-assisted)
- Why: GNSS is blocked, spaces are congested, and capture must be rapid to minimize disruption.
- Pro move: Build a simple control skeleton: a few known points per floor or per wing. Use them to constrain SLAM drift and align scans to the project coordinate system.
- Deliverable tip: Segment the cloud by system (duct, pipe, cable tray) or at least by room/zone naming. This speeds clash review and model updates.
Scenario D: Verifying structural steel placement before decking
Best fit: SLAM or tripod lidar (depending on tolerance); UAS for exterior framing
- Why: You often need quick capture in tight time windows. SLAM can be fast, but if bolt group tolerances are critical, bring in higher-accuracy methods or densify control.
- Pro move: Define a “critical features list” (base plates, column lines, embed plates) and scan those with a tighter loop and more control. Use SLAM for the rest.
Cost comparison: think in workflows, not hardware
Teams commonly underestimate ongoing costs. A better budgeting approach is “cost per accepted deliverable,” including:
- Mobilization (permits, flight approvals, traffic control)
- Field time and crew skill
- Processing time (classification, registration, QA)
- Rework risk (rescans, misalignment, missing areas)
- Downstream extraction (surfaces, linework, quantities, BIM objects)
Rule of thumb: If you repeatedly need CAD-ready surfaces and quantities, invest in repeatable control and standardized processing templates. If you mostly need visual verification and coordination, prioritize speed and usability (often SLAM) but maintain a minimum QA protocol.
Practical selection checklist (use this before you buy or rent)
- Define the tolerance that matters: Are you verifying pay quantities (percent-level) or anchor bolts (millimeter-level)?
- Map GNSS availability: If GNSS is unreliable, plan for control-assisted SLAM or static scanning tie-ins.
- Identify occlusion risk: Dense pipe racks and rebar forests require multiple passes and viewpoints—SLAM often wins, but plan loops.
- Decide your deliverable format: Surfaces (TIN/DTM), linework, or model updates. The more “interpreted” the deliverable, the more processing labor you need.
- Standardize QA: Always include check points and publish residuals. The fastest way to lose trust is to deliver a beautiful point cloud that can’t be verified.
- Plan repeat capture: If you’ll scan weekly, consistency beats perfection. Use the same control, routes, and settings so changes are real—not procedural.
Conclusion: the best workflow is usually a hybrid
UAS lidar, mobile mapping, and SLAM scanning each dominate in different construction realities: broad earthwork coverage, rapid corridor capture, and GNSS-denied interiors. Most high-performing survey programs don’t pick one—they build a hybrid toolkit with a consistent control strategy and QA standard that makes data defensible across methods.
For Swift Survey readers, the most reliable path to better outcomes is to start from the deliverable and tolerance, then work backward into access, safety, and repeatability. When your capture method matches the job’s constraints—and your QA is transparent—reality capture becomes a predictable production asset, not an experiment.
11 “Messy Data” Market Research Techniques That Reveal What People Actually Do (Not Just What They Say)
Why “messy data” is having a moment in market research
Traditional surveys and focus groups are still valuable, but they often capture what people think they do—or what they want to sound like they do. The most useful insights today frequently come from “messy” sources: behavioral traces, unstructured text, public conversation, and context-rich observation. These inputs can feel noisy, biased, or incomplete—yet when handled responsibly, they unlock patterns that clean, structured data can miss.
Below are 11 creative, highly practical techniques market researchers are using to get closer to reality. Each one is actionable for agile teams and scalable for larger programs, with tips to help you avoid common traps.
11 Messy-Data Market Research Techniques You Can Use This Quarter
1) “Receipt archaeology”: analyze real spending without asking about budgets
Instead of asking “How much do you spend on X?”, run a receipt-based study. Ask participants to upload anonymized receipts (or screenshots of order confirmations) for a set time window (e.g., 14–30 days). This method reveals brand switching, basket size, promo sensitivity, and true frequency.
- How to run it: Provide a simple upload flow and a “redaction checklist” (cover addresses, payment details). Incentivize per receipt to reduce drop-off.
- What you’ll learn: Cross-category trade-offs (e.g., buying premium coffee but discount snacks), private-label substitution, and which promotions actually move behavior.
- Example: A DTC pantry brand can see if “subscription intent” matches actual replenishment intervals—often it doesn’t.
2) “Search-to-shelf tracing”: map intent using search logs + product availability
Search data is a real-time window into needs, but it can mislead if you ignore what’s actually available. Pair keyword trends with availability/price snapshots to identify “frustrated intent” (people searching for items they can’t easily buy) and “substitution intent” (people shifting to alternatives).
- How to run it: Track top queries weekly; capture competitor availability and price at the same time; annotate major events (paydays, holidays, weather).
- Actionable insight: If searches for “gluten-free lunchbox snacks” rise while top SKUs are out of stock, demand is real—but conversion is blocked.
3) Community “micro-ethnography”: study one niche group deeply for 7 days
Instead of broad personas, do a short, deep dive into one highly relevant community: a subreddit, Discord server, Facebook group, or forum. The goal isn’t to generalize; it’s to uncover language, norms, decision triggers, and pain points you can test elsewhere.
- How to run it: Observe for 3–4 days, then run a small opt-in interview sprint with community members. Summarize in a “dictionary” of phrases and objections.
- Tip: Quote responsibly and avoid scraping private spaces without consent.
4) “Complaint mining” from support tickets to predict churn (before surveys do)
Support tickets are unglamorous but brutally honest. Tag tickets by issue type, emotion, and lifecycle stage (new user vs. power user). Patterns often emerge that correlate with churn weeks earlier than NPS dips.
- How to run it: Pull 90 days of tickets; create a lightweight taxonomy (10–15 tags); score sentiment; map to retention cohorts.
- What to look for: Repeated “workaround” language (“I had to…”) signals friction that users tolerate—until they don’t.
5) “Dark social listening”: track shares that don’t show up in analytics
A lot of word-of-mouth happens in private channels (DMs, group chats) where referral data is invisible. While you can’t (and shouldn’t) spy on private conversations, you can research “dark social” through participant diaries and share-trigger questions: “What did you send to a friend this week, and why?”
- How to run it: Use a 5-minute daily diary with one screenshot request (optional) and a “why this was share-worthy” prompt.
- Outcome: You’ll learn which product moments generate social currency (humor, deal alerts, identity signaling, usefulness).
6) “Second-screen studies”: measure what people do while they watch ads or content
Many viewers multitask: scrolling, messaging, shopping. Second-screen studies capture attention realistically. Ask participants to record their screen (with consent) during a TV show, livestream, or YouTube session and annotate what they were doing during ad breaks or brand mentions.
- What you’ll learn: Which cues pull attention back (audio stings, captions, on-screen text) and which formats get ignored.
- Practical tip: Keep sessions short (20–30 minutes) to avoid fatigue and privacy concerns.
7) “Price pain experiments”: test willingness to pay using micro-commitments
Asking “What would you pay?” often produces optimistic numbers. A better approach is to introduce small commitments: asking users to choose between bundles, lock a price for later, or allocate a fixed budget across options. This reduces hypothetical bias.
- How to run it: Create a simple choice-based survey with trade-offs (features vs. price). Add a “hold this price” option that leads to a waitlist or follow-up offer.
- Data point to track: The drop-off rate at each price tier is often more informative than the average stated price.
8) “Packaging in the wild”: intercept tests at the moment of confusion
In-store and on-shelf decisions happen fast. Run intercept research where people are actually shopping (or browsing an online category page). Ask them to find the product for a specific need, then observe where they hesitate.
- How to run it: Give a mission (“Find a low-sugar snack for a child’s lunchbox”). Note time-to-find, mis-clicks, and questions asked.
- Insight: You’ll uncover whether your label claims match how shoppers scan shelves (often they don’t).
9) “Policy-and-news signal scanning”: anticipate demand shifts tied to real-world events
Sometimes market changes aren’t about your category—they’re about the world. Build a light “signal scan” across policy announcements, labor news, and inflation updates that affect household budgets and business spending.
For example, coverage of cost-of-living pressures and consumer belt-tightening can provide context for why premium conversion is slowing, even if your product hasn’t changed. When you need a quick pulse on broader sentiment, a reputable news source can help ground your assumptions—e.g., relevant economic reporting from The Guardian’s business and economics coverage.
- How to run it: Create a monthly “context memo” that links 3–5 external signals to your KPIs (conversion, AOV, churn).
- Outcome: Better stakeholder alignment: research findings feel less “mysterious” when tied to real-world constraints.
10) “AI-assisted open-ends” with a human audit: scale qualitative without losing nuance
Open-ended responses are gold—but hard to analyze at scale. Use AI to cluster themes and extract representative quotes, then run a human audit to confirm meaning, detect sarcasm, and catch minority viewpoints that algorithms might flatten.
- Workflow: (1) Clean responses (remove PII), (2) auto-cluster, (3) label themes, (4) human review 10–20% sample per theme, (5) finalize narrative with quotes.
- Tip: Track “theme confidence” and highlight what’s uncertain rather than over-claiming.
11) “Friction diaries”: document every workaround users invent
People are incredibly creative when a product doesn’t fit their reality. A friction diary asks participants to log each time they had to “hack” your product or process: copying info into notes, using another tool, asking a colleague, abandoning a task, or delaying a purchase.
- How to run it: 7-day diary, one prompt: “What were you trying to do? What got in the way? What did you do instead?”
- What it reveals: The highest-ROI fixes are often small: unclear terminology, missing defaults, confusing plan names, checkout surprises.
Conclusion: turn “messy” inputs into clear, testable decisions
Messy data doesn’t replace surveys—it complements them. The big advantage is realism: receipts, searches, complaints, and diaries show what people actually do under real constraints (time, money, attention). If you’re building a research plan for the next quarter, pick two techniques from this list: one behavioral (like receipt archaeology or second-screen studies) and one explanatory (like friction diaries or micro-ethnography). Then connect the findings to a specific decision—pricing, positioning, packaging, onboarding, or retention—so insights don’t just sit in a slide deck.
At Swift Survey, these methods pair especially well with fast-turnaround questionnaires: use messy data to discover the “why,” then use surveys to quantify the “how many.”
How to Run a “Micro-Experiment Week” to Upgrade Your Daily Life (Without Burning Out)
Why a Micro-Experiment Week Works (Even If You’re Busy)
Most self-improvement advice fails for one simple reason: it asks you to overhaul your entire life on Monday. A Micro-Experiment Week flips that script. Instead of committing to a big habit forever, you run tiny, low-risk tests for seven days—then keep only what actually helps.
This approach is especially useful if you’re curious, easily bored, or tired of “all or nothing” routines. It also creates real data about your life, not someone else’s highlight reel.
Below is a step-by-step, casual, totally doable guide to plan, run, and review a Micro-Experiment Week—complete with examples, decision rules, and a simple way to track results without turning it into homework.
Step 1: Pick One Life Area (Not Your Entire Existence)
The biggest mistake is trying to experiment with everything at once: sleep, food, productivity, relationships, exercise, finances, and meditation. That’s not a Micro-Experiment Week—that’s chaos.
Choose one area to focus on:
- Energy (sleep, movement, caffeine timing)
- Focus (notifications, deep work blocks, meeting boundaries)
- Mood (social time, outdoor time, music, gratitude)
- Money (subscriptions, grocery strategy, impulse spending barriers)
- Household sanity (laundry flow, clutter hot spots, meal planning)
Real-world example: If you’ve been feeling “foggy,” choose Energy. If you’re drowning in tasks, choose Focus.
Step 2: Define Your “Win Metric” (Keep It Ridiculously Simple)
You need a way to tell whether an experiment worked. But you don’t need a spreadsheet that looks like a NASA dashboard.
Pick 1–2 metrics you can rate in under 10 seconds:
- Energy: “How energized do I feel right now?” (1–10) at 2pm
- Focus: “Did I get my #1 task done?” (yes/no)
- Mood: “How’s my mood?” (1–10) after dinner
- Money: “Did I spend money I didn’t plan to?” (yes/no)
Data point you can actually use: With a 1–10 rating, a change of ~1 point across multiple days is noticeable in real life. If your 2pm energy goes from a 4 to a 6 for three days in a row, that’s not random.
Step 3: Brainstorm 5–7 Micro-Experiments (Tiny Tests, Not Personality Changes)
A micro-experiment should be:
- Small (10 minutes or less per day)
- Specific (clear start/end)
- Reversible (you can stop without consequences)
Here are creative, specific micro-experiments you can steal:
Energy Experiments
- “Sunlight before screen”: 2 minutes outside within 30 minutes of waking
- “Caffeine delay”: no caffeine for the first 60 minutes after waking
- “2pm walk reset”: 8-minute walk right after lunch
Focus Experiments
- “Notification quarantine”: phone in another room for 45 minutes
- “Single-tab sprint”: 25 minutes with only one browser tab allowed
- “Meeting speed bump”: ask “What decision do we need by the end?” at the start of every meeting
Mood Experiments
- “Friendship drip”: send one voice note (not text) to a friend
- “Micro-joy menu”: pick one tiny treat daily (tea ritual, music, 10 min hobby)
Tip: If a micro-experiment feels like a big deal, it’s too big. Shrink it until it sounds almost laughably easy.
Step 4: Write a 7-Day Schedule (One Experiment Per Day)
Give each day exactly one primary experiment. You can keep your normal routine otherwise.
Example schedule (Focus theme):
- Day 1: Notification quarantine (45 minutes)
- Day 2: Single-tab sprint (25 minutes)
- Day 3: “Start ugly” rule: begin your #1 task for 5 minutes, no prepping
- Day 4: Calendar gate: no meetings before 10:30am
- Day 5: End-of-day shutdown: write tomorrow’s top 3 and stop
- Day 6: Inbox batching: check email only 2 times
- Day 7: “Noise design”: choose one background mode (silence, music, or white noise) and keep it consistent
Actionable tip: Put the experiment name into your calendar as a 10-minute “appointment” so it doesn’t disappear under real life.
Step 5: Set Your Rules Before You Start (So You Don’t Negotiate With Yourself)
Make three rules—quick and clear:
- Rule 1: If I miss a day, I don’t “make up” anything. I just continue.
- Rule 2: I track my win metric once per day, same time.
- Rule 3: I’m testing the experiment, not judging myself.
This matters because your brain will try to turn the week into a moral referendum. Don’t let it.
Step 6: Track Results in 30 Seconds (Use Notes, Not a Complex App)
Open your notes app and create a template like this:
- Date + experiment name
- Win metric: (1–10 or yes/no)
- One sentence: “What made this easier/harder?”
Example entry: “Wed — Single-tab sprint. Focus: Yes. Felt weirdly calming; biggest issue was Slack pings.”
That’s enough. You’re collecting signals, not writing a memoir.
Step 7: Add One “Context Note” for Better Data (Sleep, Stress, or Schedule)
This is the secret sauce: one quick context marker helps you interpret results honestly.
- Slept <6 hours (yes/no)
- High-stress day (yes/no)
- Travel/social overload (yes/no)
Why it matters: If a micro-experiment “fails” on a day you slept 4 hours and had back-to-back meetings, it might not be the experiment’s fault. Or it might still be useful because it held up under chaos.
Step 8: Use a “Keep, Tweak, Trash” Review on Day 7
At the end of the week, you’re not asking, “Did I become a new person?” You’re asking, “What do I keep?”
Create three buckets:
- Keep: noticeably helpful, low effort
- Tweak: helpful but needs adjustment
- Trash: annoying, ineffective, or made things worse
Decision rule: Keep anything that improved your win metric by ~1 point or more or made the day feel meaningfully easier.
Step 9: Turn the Best Experiment Into a 14-Day “Pilot Habit”
Don’t try to keep all the winners. Pick one and run it for two more weeks.
Why 14 days? It’s long enough to see if it holds up across different kinds of days (busy days, weekends, low-motivation days). It also feels finite, which keeps you from rebelling against your own plan.
Example: If “2pm walk reset” boosted your energy from 5 to 7 most days, keep it. But tweak it if needed: “6-minute walk when it rains” or “walk while taking a call.”
Step 10: Upgrade Your Experiment Quality With Better Inputs (Optional, But Powerful)
If you want your experiments to be evidence-informed, borrow ideas from credible reporting and research summaries. One practical way to find timely behavior and wellness insights is to skim health and science coverage from major outlets. For example, The New York Times health section often compiles expert commentary and recent studies into readable takeaways you can translate into micro-experiments (like sleep timing, walking habits, or attention management strategies).
Actionable tip: When you read a claim, convert it into a testable prompt: “What’s the smallest version of this I can try for one day?”
Step 11: Real-World Micro-Experiment Week Examples (So You Can Copy-Paste)
Example A: The “Afternoon Crash” Fix
- Win metric: 2pm energy (1–10)
- Experiments tested: 2pm walk, caffeine delay, protein-at-lunch, 10-minute power nap, screens-off lunch
- Result pattern: Walk + protein lunch improved energy by ~2 points on 4/7 days
- Keep: 8-minute walk after lunch
- Tweak: caffeine delay to 30 minutes instead of 60
Example B: The “I Can’t Start Tasks” Week
- Win metric: #1 task done (yes/no)
- Experiments tested: 5-minute “start ugly,” single-tab sprint, phone in other room, body-doubling (work next to someone), write the first sentence only
- Result pattern: “Start ugly” succeeded even on high-stress days
- Keep: Start ugly + 25-minute timer
Step 12: Common Pitfalls (And How to Avoid Them)
- Pitfall: Making experiments too hard. Fix: Cut the time in half.
- Pitfall: Changing three things at once. Fix: One experiment per day.
- Pitfall: Tracking too much. Fix: One metric, one sentence.
- Pitfall: Quitting after a “bad day.” Fix: Add a context note and continue.
Conclusion: A Week of Tiny Tests Beats a Year of Vague Intentions
A Micro-Experiment Week is basically a cheat code for personal growth: low pressure, high learning, and surprisingly effective. You’re not forcing motivation—you’re designing a week where results show up on their own.
Pick one life area, run seven tiny tests, track one simple metric, and keep only what works. In seven days, you’ll know more about your energy, focus, mood, or money habits than you’d learn from months of “I should really…”
And the best part? If an experiment flops, you didn’t fail—you just saved yourself from committing to the wrong habit for the next six months.
Synthetic Data for Surveys in 2026: 11 Practical Tactics Data Teams Use to Boost Insights Without Breaking Privacy
Why “synthetic survey data” is suddenly the most useful tool in the data services toolkit
Survey programs are getting squeezed from both sides: response rates are harder to sustain, while privacy expectations and regulatory scrutiny keep rising. At the same time, teams are expected to deliver segmentation, forecasting, and personalization faster than ever. One quietly powerful workaround has moved from niche to mainstream: synthetic data—artificially generated records that mimic the statistical properties of real responses without exposing individuals.
For Swift Survey readers, synthetic data isn’t about faking results. It’s about creating safe, scalable “training and testing” versions of your survey datasets, so analysts can build models, QA pipelines, validate dashboards, and share insights broadly—without moving sensitive microdata around.
This roundup collects practical tactics, checks, and resources that real data teams use when they apply synthetic data to survey workflows. The focus is intentionally specific: survey-derived synthetic data (attitudinal, behavioral, demographic, and open-text-derived features) in a modern data services environment.
Roundup: 11 field-tested ways to use synthetic data in survey operations
1) Use synthetic data to unblock cross-team access (without emailing CSVs)
Many organizations still bottleneck on “who can see what.” A common pattern is that the data team holds the raw respondent-level file, while product, marketing, and operations wait for extracts.
- Tactic: Produce a synthetic copy of the survey table(s) for broad internal access. Keep raw microdata locked down; let teams explore synthetic in BI tools.
- Actionable tip: Preserve key distributions (age bands, NPS buckets, segment labels) and correlation structures (e.g., satisfaction vs. renewal intent) so dashboards behave realistically.
- Real-world example: A customer experience team can prototype a churn-risk dashboard on synthetic data while legal reviews access requests for raw data—saving days or weeks.
2) Create “safe sandboxes” for vendors and agencies
Outsourced analytics, call-center optimization, and media measurement often require sharing data. Synthetic data is increasingly used as a negotiation-friendly alternative to “give us everything.”
- Tactic: Share synthetic respondent-level data for scoping, pipeline development, and early modeling; only move real data into a controlled environment once contracts, DPAs, and security reviews are complete.
- Actionable tip: Add a field-level documentation sheet describing what is synthetic, what is derived, and what is masked or truncated.
3) Stress-test weighting, raking, and post-stratification workflows
Weighting is where survey pipelines often become fragile: one missing category, one unexpected skew, and your raking algorithm fails or produces extreme weights.
- Tactic: Generate synthetic datasets with controlled “edge cases”: rare strata, missing cells, or overrepresented groups.
- Actionable tip: Build automated tests that flag weight caps, effective sample size drops, and unstable convergence—then run them nightly on synthetic “challenge” datasets.
- Data point to watch: Track effective sample size (ESS) after weighting; large drops can indicate overly aggressive adjustment.
4) Validate longitudinal survey logic before fielding your next wave
Tracking studies (monthly NPS, quarterly brand trackers, employee pulses) suffer when questionnaire changes break trend comparability.
- Tactic: Generate synthetic “Wave T” and “Wave T+1” datasets and run your trend dashboards as if the new wave has launched.
- Actionable tip: Introduce synthetic structural breaks intentionally (e.g., a new response option) to see how reporting behaves.
5) Build privacy-preserving micro-simulations for scenario planning
Executives ask “What happens if we improve shipping satisfaction by 10 points?” or “Which segments drive NPS decline?” Synthetic datasets can power micro-simulations without touching raw respondents.
- Tactic: Fit a model on real data in a controlled environment, then run scenario simulations on synthetic populations that maintain segment structure.
- Actionable tip: Produce segment-level effect summaries (uplift by segment) that are stable across synthetic draws—if they vary wildly, your model may be overfit.
6) Generate realistic training data for text pipelines (without leaking personal info)
Open-ends can include names, phone numbers, addresses, or highly identifying details. Even if you strip obvious PII, re-identification risks remain when combined with other fields.
- Tactic: Convert open-text into features (topics, sentiment scores, embeddings) and synthesize the features rather than sharing verbatim text.
- Actionable tip: If your team must work with raw text, build a redaction layer first; then generate synthetic text only from de-identified content, and never preserve rare phrases verbatim.
7) Detect “linkage risk” early by testing what an attacker could infer
Synthetic data is not automatically safe. The risk depends on how it’s generated and what auxiliary data an attacker might have.
- Tactic: Run membership inference and attribute inference tests (or simpler proxies) to estimate whether synthetic records reveal too much about individuals in the training set.
- Actionable tip: Start with a conservative rule: if a combination of quasi-identifiers (ZIP3 + age + rare job title) appears too rarely in the real data, coarsen or suppress it before synthesizing.
8) Calibrate synthetic data quality with “utility checks” that matter to survey stakeholders
Data scientists may focus on KL divergence or distance metrics, but survey programs live or die by business-facing outputs: segment rankings, topline KPIs, and driver analysis.
- Tactic: Define a utility scorecard before you generate anything.
- Suggested scorecard items:
- Topline KPI alignment (e.g., NPS, CSAT, favorability) within a tolerance band
- Segment order preservation (are the top 3 segments still top 3?)
- Driver stability (key predictors of satisfaction remain consistent)
- Rare category behavior (does synthetic data invent impossible combinations?)
9) Use synthetic data to benchmark fraud and data quality rules
Survey data services increasingly contend with speeders, straight-liners, bots, duplicate respondents, and inconsistent answers.
- Tactic: Generate synthetic “good” respondents and separately generate synthetic “bad” patterns (e.g., identical grids, impossible time-to-complete) to validate detection logic.
- Actionable tip: Treat fraud rules like unit tests: each rule should trigger on synthetic bad cases and not trigger on synthetic good cases.
10) Establish a governance pattern: “synthetic-by-default” for dev, “real-by-exception” for prod
One of the most effective cultural shifts is to make synthetic data the default dataset for development work. Real respondent-level access becomes an exception with justification, approvals, and audit logs.
- Tactic: Maintain three tiers: (1) synthetic dev, (2) aggregated reporting, (3) raw restricted.
- Actionable tip: Put time limits on raw access (e.g., 14 days), and require outputs to be aggregated or privacy-reviewed before sharing.
11) Make synthetic data credible by communicating what it is (and what it is not)
Synthetic data can cause confusion: stakeholders may treat it as “fake survey results.” The cure is clear labeling and education.
- Tactic: Add a banner in dashboards and datasets: “Synthetic data for development/testing—do not use for business decisions.”
- Actionable tip: Provide two short examples in your documentation: one showing a correct use (QA a dashboard) and one showing an incorrect use (report quarterly NPS externally).
Tools, methods, and selection criteria (a practical buyer’s checklist)
There isn’t one “best” synthetic approach for surveys. Your choice depends on data type, risk tolerance, and the questions the organization needs to answer.
- Tabular survey data (categorical + ordinal): Look for generators that handle mixed data types, preserve correlations, and can enforce constraints (e.g., skip logic consistency).
- Weighted survey designs: Decide whether to synthesize pre-weight or post-weight distributions; document the choice and validate KPI drift.
- Small samples and rare groups: Be cautious—synthetic data can either overfit or erase rare but important populations. Consider coarsening categories before synthesis.
- Governance features: Audit logs, reproducibility (seed control), and clear data lineage matter as much as the model itself.
If your organization is still forming its view on privacy and data sharing, it’s worth following credible reporting on real-world data misuse and why anonymization can fail in practice. For ongoing coverage and case studies that help ground governance discussions in reality, see BBC News reporting on data privacy.
Implementation blueprint: a fast, safe pilot in 2–3 weeks
Week 1: Define “utility” and “risk” success criteria
- Pick 3–5 outputs that must match: e.g., NPS overall, NPS by region, key driver ranking, and a segmentation profile.
- Pick 3–5 risk checks: e.g., uniqueness of quasi-identifiers, suppression of rare categories, and a policy for minimum cell sizes.
Week 2: Generate synthetic data + run scorecards
- Start with one survey wave and one core reporting dataset.
- Run automated scorecards and record KPI drift.
- Iterate: coarsen categories, apply constraints, or adjust privacy parameters until the scorecard passes.
Week 3: Integrate into your data services workflow
- Publish synthetic datasets to a dev schema and connect BI tools.
- Update SOPs: when to use synthetic vs. aggregated vs. raw.
- Train stakeholders: what synthetic data is for, and how to interpret it.
Conclusion: synthetic data is a multiplier for survey analytics—when governed like a product
Synthetic data for surveys is most valuable when you treat it as a managed data service: defined use cases, measurable quality, repeatable generation, and explicit privacy constraints. Done well, it accelerates dashboard development, enables safer collaboration, improves pipeline reliability, and reduces the everyday friction of sharing respondent-level information. Done casually, it can mislead stakeholders or create a false sense of safety.
The teams getting the biggest wins in 2026 are not the ones generating the fanciest synthetic records—they’re the ones pairing synthetic datasets with clear utility scorecards, rigorous risk checks, and a “synthetic-by-default” operating model.
Heat-Smart Surveying: FAQs on Measuring, Mitigating, and Scheduling Construction Layout in Extreme Heat
What is “heat-smart” surveying, and why is it suddenly such a big deal?
“Heat-smart” surveying is the practice of planning and executing field measurements with the explicit goal of reducing heat-related errors and protecting crews during high-temperature conditions. It’s become a hot topic (literally) because many projects now face more frequent and intense heat waves, longer hot seasons, and tighter schedules that don’t always allow easy weather delays.
From a surveying and construction perspective, extreme heat creates a two-part problem:
- Human factors: fatigue, dehydration, reduced focus, and higher safety risk.
- Measurement factors: thermal expansion of materials, heat shimmer (atmospheric refraction), electronic performance drift, and unstable tripod setups on baked ground.
Heat-smart surveying doesn’t require fancy new gear; it’s often about adjusting workflows, calibrations, timing, and documentation so your results remain defensible and repeatable.
How does extreme heat actually change survey measurements?
Heat affects measurements through the materials you measure, the air you measure through, and the equipment doing the measuring.
1) Thermal expansion of materials (steel, concrete, even tape)
Most crews know steel expands when hot, but the important part is how much and when it matters. Steel’s coefficient of thermal expansion is roughly 11–13 microstrain/°C. A practical rule of thumb:
- About 0.12 mm per meter per 10°C for steel.
Real-world example: If you’re setting anchor bolt centers using a steel tape over a 30 m span, and the tape temperature is 20°C hotter than the tape’s standard calibration temperature, the apparent length can be off by roughly:
- 0.12 mm/m per 10°C × 2 × 30 m ≈ 7.2 mm
That’s enough to cause fit-up pain for structural steel, precast panels, or equipment skids.
2) Atmospheric refraction and “heat shimmer” (especially near pavement)
When the ground is hot, the air above it forms layers of different densities. Light bends as it passes through these layers. For optical lines of sight (and even some EDM paths), this can introduce angle and distance anomalies—often worst in mid-afternoon across asphalt, concrete, or bare soil.
Actionable tip: If you must shoot across a large hot surface, raise the line of sight (higher tripod, taller rod, or offset the shot path) so you’re not measuring in the most turbulent air layer closest to the ground.
3) Instrument performance and stability
Total stations, GNSS receivers, batteries, and tribrachs all behave differently in heat. Battery capacity drops, plastics soften slightly, and instrument compensation systems can be stressed when the sun beats directly on the housing.
Actionable tip: Shade the instrument between shots (even using a small reflective cover) and avoid leaving it baking in a closed vehicle. Let equipment acclimate before high-precision work.
What types of construction surveying are most vulnerable to heat-related error?
Heat can affect any field task, but these are most sensitive:
- Long baseline layout: control extensions, long offsets, and setting large grids on hot days.
- Vertical control transfer: optical leveling over shimmering surfaces.
- As-built checks for steel and embeds: tight tolerances meet thermally expanding members.
- Bridge and roadway work: measurements across asphalt or concrete that radiates heat.
- Industrial installs: equipment skids, pipe racks, and alignment tasks where millimeters matter.
Practical note: In many cases the biggest errors show up not because the instrument is “wrong,” but because the site conditions differ from the assumptions used when the control and tolerances were established.
How can we schedule heat-smart surveying without blowing the construction program?
Scheduling is often the cheapest accuracy upgrade you can buy. A heat-smart plan prioritizes precision work when conditions are calm and cool.
- Do high-precision control work early: Aim for sunrise to late morning for control densification and critical layout.
- Reserve afternoons for lower-risk tasks: stakeouts with larger tolerances, site walks, documentation, and office reductions.
- Use “split shifts” during heat waves: An early shift plus a short evening window can outperform one long midday push.
- Lock in temperature-dependent tasks: If you must measure steel or long tape distances, do it when material temps are stable (often early morning) rather than during peak sun.
Real-world workflow example: On a slab-on-grade project, a crew might set primary control and slab pour layout by 10 a.m., then switch to punchlist as-builts, scanning prep, or QA paperwork during peak heat.
What field checks catch heat-induced issues before they become rework?
Heat errors often masquerade as random noise. Quick verification steps make problems visible.
- Close loops more often: Treat hot days like “high-risk” days—run frequent backsight checks and close traverses sooner.
- Use redundant observations: Re-shoot critical points from a second setup or different time window.
- Track residual patterns: If errors trend in one direction after noon, that’s a clue you’re seeing refraction or thermal effects.
- Document surface type: Shots across asphalt at 3 p.m. aren’t equivalent to shots across grass at 9 a.m. Log it.
Actionable tip: Build a “heat flag” into your field notes: air temperature, surface type (asphalt/concrete/soil), cloud cover, and time of day for any control or tolerance-tight layout.
Do GNSS measurements get worse in heat, or is that mostly an optical total station problem?
GNSS is less sensitive to near-ground optical refraction, but heat can still degrade results indirectly:
- Battery and electronics: hot batteries can deliver shorter run time and more voltage sag.
- Tripod/rod instability: baked ground can soften or crack; bipods can creep.
- Multipath changes: heat haze isn’t “multipath,” but high-traffic summer environments can increase reflective interference (vehicles, temporary metal, staged materials).
- Human error increases: rushed setups, skipped level bubbles, and shortened occupation times happen when crews are trying to “beat the heat.”
Best practice: On hot days, slightly increase occupation time for control points and be strict about rod level and fixed-height setups. If you’re using RTK/Network RTK, confirm your localization and monitor quality indicators (PDOP, ambiguity status, residuals).
How should we handle temperature corrections for tape, EDM, and critical dimensions?
Temperature corrections range from “ignore it” to “mandatory,” depending on tolerances.
For tape measurements
- Measure tape temperature (not just air temperature). A tape in the sun can be significantly hotter than ambient.
- Use calibrated tapes and know the standard temperature from the certificate.
- Reduce sun exposure: shade the tape, or use invar/low-expansion solutions when justified.
For EDM/total station distances
- Input correct PPM settings (temperature and pressure) if your instrument uses them.
- Avoid long low lines of sight over hot surfaces where refractive gradients dominate.
Actionable tip: If your project involves tight steel or equipment tolerances, agree in writing (survey plan or QC plan) on how temperature corrections will be handled—especially if dimensions are compared to shop drawings produced at a different assumed temperature.
What’s a practical heat-safety protocol for survey crews that still keeps production moving?
Safety and productivity aren’t enemies; heat illness is a guaranteed productivity killer. A field-ready protocol usually includes:
- Work/rest cycles: pre-plan short rests rather than waiting for exhaustion.
- Hydration standard: don’t rely on “drink when thirsty.” Set minimum intake guidelines and keep water accessible (not in the truck a quarter-mile away).
- Cooling tactics: shade, cooling towels, and breathable PPE options where allowed.
- Buddy checks: heat stress is easier to spot in someone else than in yourself.
- Heat trigger plan: at a defined heat index threshold, automatically shift to earlier hours or lower-risk tasks.
For broader context on how heat is affecting work and daily life in many regions, major news outlets have been tracking heat waves and their impacts; a helpful starting point for general reporting and background is The New York Times climate and weather coverage.
How do we explain heat-related survey variance to a GC or owner without sounding like we’re making excuses?
The key is to frame heat as a manageable quality variable, not a vague complaint.
- Use records: show time-of-day, temperature, surface type, and check-shot residuals.
- Offer options: propose a re-check window (early morning), or a redundant method (GNSS + total station, or short-range resection).
- Connect to tolerance: “This embed layout requires ±3 mm; afternoon refraction across the slab increases risk. We recommend confirming at 7–9 a.m.”
- Document decisions: if the team chooses to proceed in high heat, note the condition and the agreed approach.
Real-world example: On an industrial foundation, if afternoon shots show a consistent 5–8 mm shift compared to morning control checks, the conversation becomes straightforward: either accept the risk, change measurement geometry, or reschedule critical layout.
What are the best “low-cost” upgrades for heat-smart surveying?
You don’t need a new robot or scanner to improve hot-weather outcomes. Consider these upgrades first:
- Reflective instrument shade (lightweight cover kept in the field kit).
- Ground plates or tripod shoes for soft or cracking soils.
- Better field logging (simple template for heat conditions and check shots).
- Extra batteries stored properly (avoid cooking them in the cab).
- Defined “critical shot” checklist so crews don’t skip verification when uncomfortable.
Conclusion: What’s the takeaway for construction teams working through hotter seasons?
Extreme heat doesn’t have to mean sloppy layout or constant rework. The crews who perform best in hot conditions tend to do three things consistently: (1) schedule precision work during stable, cooler windows; (2) build redundancy and documentation into their field process; and (3) treat heat safety as part of quality control, not a separate issue.
If you adopt even a basic heat-smart playbook—temperature-aware planning, smarter line-of-sight choices, frequent closure checks, and clear communication—you’ll protect your people and deliver measurements the project can trust.
Synthetic Respondents in Market Research: An FAQ on When AI Personas Help (and When They Mislead)
What are “synthetic respondents,” and why are they suddenly everywhere?
Synthetic respondents (also called AI respondents, synthetic panels, or digital twins) are AI-generated “participants” that simulate how certain consumer segments might answer survey questions, react to product concepts, or choose between offers. They’re typically built using a mix of:
- Large language models (LLMs) that generate human-like responses
- Training data (public data, proprietary customer data, past surveys, CRM interactions, reviews, etc.)
- Constraints (demographics, behaviors, location, income, brand usage) to shape the “persona”
They’re trending because teams want faster iteration cycles (hours, not weeks), lower costs per concept test, and a way to explore early hypotheses before paying for live sample. They’re also appealing when quality issues in online panels—like bots, professional respondents, and speeding—make researchers nervous.
Is this the same as “synthetic data”?
Related, but not identical. Synthetic data usually means artificially generated datasets that mimic the statistical properties of real datasets (e.g., customer records or transaction logs) without exposing real personal information. Synthetic respondents are about generating answers and rationales as if a person responded to a survey or interview.
In practice, synthetic respondents may be created from synthetic data, and synthetic data may be used to power synthetic respondents. But when market researchers talk about “AI respondents,” they’re usually referring to simulated participant responses to research instruments.
What market research problems can synthetic respondents solve well?
Used carefully, synthetic respondents can be very useful for directional insight and workflow acceleration. Here are scenarios where they tend to help most:
- Early-stage concept screening: Rapidly test 10–30 rough ideas to identify the 3–5 worth validating with humans.
- Questionnaire debugging: Run synthetic “dry runs” to spot confusing wording, missing answer options, or leading questions.
- Message and positioning exploration: Stress-test different value propositions and see how different personas interpret them.
- Market education checks: Explore what a segment likely knows (and doesn’t) about a new category to shape survey context.
- Internal alignment: Provide fast, structured narratives that help stakeholders understand target segments before fieldwork.
Practical tip: Treat synthetic outputs like an “idea generator” and “risk radar,” not a final measurement tool. They can help you avoid spending real sample on obviously weak directions.
Where do synthetic respondents usually go wrong?
Synthetic respondents can fail in ways that look convincing unless you know what to watch for. Common pitfalls include:
- False precision: AI can generate confident-sounding percentages or rankings without a real sampling frame.
- Training-data bias: If the model overrepresents vocal online populations, you’ll get skewed “opinions.”
- Mode effects: People behave differently in real purchase contexts than in text-based simulated responses.
- Novelty blindness: AI often regurgitates familiar patterns, underestimating how consumers react to truly new ideas.
- Missing “messiness”: Real respondents contradict themselves; synthetic ones may sound too coherent.
In other words: synthetic respondents are great at producing plausible answers, but plausibility isn’t the same as validity.
Can synthetic respondents replace live survey sample?
For most decision-making, no—not if you need defensible, generalizable measurement. Live sample remains essential when you need:
- Incidence and penetration estimates (e.g., “What % of shoppers bought X in the last 30 days?”)
- Trend tracking (brand health, NPS, awareness)
- Pricing measurement where elasticities and demand curves must reflect real market response
- Claims support for investor decks, regulatory contexts, or high-stakes strategy
That said, synthetic respondents can reduce your total spend by helping you focus live research where it matters most, and by improving instruments before launch.
What are some real-world ways teams use synthetic respondents alongside human research?
Here are three practical hybrid patterns that market research teams are using:
- “AI pretest” then human validation: Run 200–500 synthetic completes to identify likely drivers, then field a smaller (but high-quality) human study to confirm.
- Segment hypothesis exploration: Use synthetic personas to explore how different customer types might respond, then recruit real respondents matching the most important segments.
- Qual acceleration: Use synthetic “interviews” to refine discussion guides and probe paths before scheduling real IDIs.
Example: A beverage startup testing three functional drink concepts might use synthetic respondents to find which claims (e.g., “focus,” “calm,” “gut health”) trigger skepticism. The team then uses real sample to measure claim believability and purchase intent, focusing only on the top two concepts and the highest-risk claims.
How should I evaluate the quality of a synthetic respondent approach?
Ask vendors (or your internal data science team) for specifics. Useful evaluation questions include:
- What data sources are used? Are outputs grounded in your historical research, first-party customer data, or generic internet text?
- How are personas constrained? Can you lock demographics, behaviors, and category usage, or is it free-form generation?
- How is uncertainty handled? Do they provide confidence bands, scenario ranges, or sensitivity checks?
- Can you reproduce results? If you re-run with the same settings, do you get similar directional outcomes?
- What benchmarks exist? Have they compared synthetic outputs vs. real survey results for your category?
Actionable tip: Run a “back-test.” Take a past study where you already know the human results, then see how close synthetic respondents get on the same questionnaire. Track gaps by segment and question type (behavioral vs. attitudinal vs. price).
What kinds of questions are safest to ask synthetic respondents?
Not all question types behave the same. Generally safer:
- Interpretation questions: “What does this message mean to you?”
- Objection mining: “What concerns would you have about this product?”
- Feature tradeoff reasoning: “Why would you pick A over B?” (directional only)
Higher-risk for synthetic respondents:
- Precise incidence/behavior: “How many times did you buy X last month?”
- Any question requiring real constraints: actual budgets, availability, household decision dynamics
- Experimental measurement claims: “This increases purchase intent by 12 points” (without real sample)
How do I prevent “AI respondents” from just echoing stereotypes?
This is a big issue. Synthetic personas can become caricatures if you only define them by age/income/location. To reduce stereotyping:
- Define personas behaviorally: category frequency, brand repertoire, shopping channel, deal sensitivity, and priorities.
- Use counterfactual prompts: Ask the model to generate responses from “high-income but value-driven” or “Gen Z with low social media usage.”
- Force variability: Request multiple “sub-personas” within a segment, including edge cases.
- Validate with reality checks: Compare synthetic segment claims to known external facts (market shares, adoption rates, macro trends).
If you need credible external context on industries, pricing pressures, or consumer sentiment drivers, reading timely reporting can help anchor your hypotheses. For example, Reuters market coverage is a useful way to cross-check what’s happening in supply chains, commodity costs, and major brand moves before you interpret any model-generated “opinions.”
What data points should I track if I pilot synthetic respondents?
To make the pilot meaningful, set up a scorecard. Track:
- Speed: time from brief to insight (hours/days saved)
- Cost: reduction in exploratory sample and rework
- Instrument quality: fewer survey edits mid-field, higher completion rates, lower drop-off
- Predictive validity (where possible): correlation between synthetic directional winners and real-world outcomes (A/B tests, sales lift, click-through)
- Decision confidence: stakeholder alignment, fewer “opinion battles,” clearer next steps
Concrete approach: For 3 upcoming projects, run synthetic first, document the top 3 recommendations, then compare against what the human study and downstream performance data show.
Are there ethical or privacy concerns with synthetic respondents?
Yes—especially if you’re using first-party customer data to ground personas. Key considerations:
- Consent and permitted use: Ensure your data governance policies allow model training or retrieval for research purposes.
- Re-identification risk: Avoid generating outputs that could inadvertently resemble specific real individuals.
- Disclosure: Internally label synthetic findings clearly so they’re not mistaken for human survey results.
- Bias audits: Check outputs for systematic differences that disadvantage protected groups or misrepresent them.
If you’re in a regulated industry (health, finance, children’s products), involve legal/compliance early and document your method.
What’s a simple, practical workflow for using synthetic respondents on my next study?
Here’s a lightweight process that works well for many teams:
- Step 1: Define the decision. Example: “Select one of three packaging directions to validate with shoppers.”
- Step 2: Build 4–6 behavior-based personas. Include a loyalist, switcher, value seeker, premium buyer, and category light user.
- Step 3: Run a synthetic pretest. Ask interpretation, objection, and clarity questions. Identify confusing claims and missing answer options.
- Step 4: Revise the instrument. Tighten wording, add response options, and remove leading phrases.
- Step 5: Field human research. Use quality controls (attention checks, speeders, deduping) and ensure sample matches your target incidence.
- Step 6: Compare + learn. Document where synthetic aligned and where it diverged, then update your internal best practices.
Conclusion: Should market researchers embrace synthetic respondents?
Synthetic respondents are best viewed as a new research assistant—excellent for speeding up exploration, improving surveys before launch, and generating hypotheses you can test. They’re not a replacement for rigorous human sampling when you need accurate measurement, trend tracking, or defensible numbers.
For teams at Swift Survey and beyond, the winning approach is usually hybrid: use synthetic respondents to move faster and reduce wasted spend, then use high-quality human research to validate what matters. If you pilot thoughtfully—back-testing, tracking predictive validity, and clearly labeling synthetic findings—you’ll get the speed benefits without mistaking simulation for reality.
Paper, App, or Voice Note? A No-Fluff Comparison of 5 “Second Brain” Setups for Busy People
Why “second brain” systems are trending (and why most of them fail)
Between overflowing inboxes, scattered meeting notes, and the constant drip of new tasks, many people are turning to “second brain” systems—simple ways to capture information, organize it, and retrieve it when it matters. The appeal is obvious: offload mental clutter, make decisions faster, and avoid repeating the same research. The problem is that advice online often assumes you have time to maintain an intricate personal knowledge base. Most people don’t.
This comparison breaks down five practical “second brain” setups that real people actually stick with: paper notebook, notes app, task manager, voice-first capture, and email-as-command-center. You’ll see where each approach shines, where it collapses, and how to choose based on your work style—not on hype.
Quick definition: what counts as a “second brain”?
A usable second brain has three functions:
- Capture ideas, tasks, and reference material quickly
- Organize so you can find things later (with minimal upkeep)
- Review routinely so captured info becomes action or insight
If a system doesn’t support all three, you’ll end up with a graveyard of notes that feels “productive” but doesn’t improve outcomes.
Comparison #1: The Paper-First Second Brain (one notebook + a weekly review)
Best for
People who think better on paper, want fewer digital distractions, or work in environments where devices aren’t always practical (workshops, healthcare, field jobs).
How it works
- Use one notebook (not five) for everything: tasks, meeting notes, ideas.
- Mark tasks with a symbol (e.g., checkbox) and decisions with another (e.g., double underline).
- Do a 15-minute weekly review: migrate unfinished tasks to next week, circle key decisions, and create a short “Top 5” list.
Strengths
- Fast capture and low cognitive overhead
- Better focus: paper reduces the temptation to multitask
- Excellent for memory: many people recall handwritten notes more easily
Weaknesses
- Search is manual (unless you scan)
- Sharing requires extra steps
- Risk of loss if you misplace it
Real-world example
A team lead on a factory floor may not be able to pull out a laptop between line checks. A single notebook plus a Friday review (migrating tasks into Monday’s plan) often beats any app-based system in adherence.
Actionable tips to make it stick
- Write the date on every page for future reference.
- Create a two-page index at the front: add page numbers for key projects.
- Don’t try to categorize everything—just capture and review weekly.
Comparison #2: The Notes-App Knowledge Hub (searchable notes + light tagging)
Best for
People who handle lots of reference material—policies, client context, research links, procedures—and need fast search.
How it works
- Use one notes app (native Notes, Evernote, OneNote, Notion, Obsidian—any can work).
- Keep structure simple: 5–8 top-level folders (e.g., Work, Personal, Finance, Health, Learning).
- Use light tagging only when it improves retrieval (e.g., “#template,” “#meeting,” “#howto”).
Strengths
- Search is powerful: find a detail in seconds
- Easy to attach files, screenshots, links
- Works well for checklists and reusable templates
Weaknesses
- People overbuild structures (too many folders/tags)
- Notes can become “passive storage” without review
- Some tools encourage complexity (databases, widgets) that increase maintenance
Real-world data point
Many people underestimate how much time gets lost to re-finding information. One practical benchmark: if you spend even 5 minutes per workday hunting for notes, that’s about 20 hours a year (based on ~240 workdays). A well-run notes hub can win simply by improving retrieval speed.
Actionable tips
- Create three default note templates: Meeting, Decision Log, Project Brief.
- Every note should begin with a one-line summary: “This note is for…”
- Schedule a monthly clean-up to archive or merge duplicates.
Comparison #3: The Task-Manager “Command Center” (tasks first, notes second)
Best for
People whose biggest pain is not information overload, but follow-through: missed deadlines, dropped handoffs, unclear next actions.
How it works
- Choose a task manager you’ll open daily (Todoist, Microsoft To Do, Things, Asana, Trello, etc.).
- Write tasks as next actions (“Email Alex the draft,” not “Marketing”).
- Use due dates sparingly; rely more on daily planning and priorities.
- Link or attach reference notes only when necessary.
Strengths
- Turns intentions into scheduled action
- Supports recurring tasks and reminders
- Great for collaborative accountability
Weaknesses
- Can become a “task graveyard” if you over-capture
- Some people mistake sorting tasks for doing work
- Reference material can feel awkward compared to a notes app
Real-world example
A freelancer juggling 6–10 clients often benefits from a task-first system. Each client gets a project board or list; the daily plan chooses 3–5 outcomes. Instead of saving long research in the task tool, they store it in a notes app and link it.
Actionable tips
- Set a cap: no more than 10 tasks in your “Today” view.
- Create a list called “Waiting For” (to track delegated items).
- Hold a 10-minute end-of-day shutdown to pick tomorrow’s top tasks.
Comparison #4: The Voice-First Capture System (dictation + automated summaries)
Best for
People who get ideas while commuting, walking, caregiving, or doing hands-on work—when typing isn’t convenient.
How it works
- Capture by voice: phone voice memos, assistant диктation, or a voice-note app.
- Transcribe automatically (built-in transcription or a transcription service).
- Convert transcripts into: (1) tasks, (2) a short summary, or (3) a decision record.
Strengths
- Extremely low friction—capture is fast
- More natural for some thinkers (speaking clarifies ideas)
- Helps when you’re away from a screen
Weaknesses
- Raw audio is hard to search without transcription
- Can create clutter if you don’t process recordings regularly
- Privacy considerations in public spaces
Real-world example
A project manager leaving back-to-back meetings can record a 60-second voice note: “Decision: ship v2 with feature flag. Risks: performance. Next actions: ask Sam for load test by Thursday.” Transcribed into a single note, that becomes searchable and actionable.
Actionable tips
- Use a standard structure: Context → Decision → Next actions.
- Process voice notes daily or they pile up within a week.
- Keep recordings short (30–90 seconds) to reduce processing cost.
Comparison #5: Email-as-Second-Brain (labels, rules, and “send to self” workflows)
Best for
People whose work already happens in email and who need a pragmatic system without adding another app.
How it works
- Create 3–6 labels/folders: Action, Waiting, Read/Review, Receipts, Reference.
- Use rules/filters to automatically route newsletters and bills.
- Forward key info to yourself with a clear subject prefix: “TASK:”, “NOTE:”, “DECISION:”.
Strengths
- No new tools—high adoption
- Email search is robust
- Easy to keep context (threads, attachments)
Weaknesses
- Mixes tasks with communication (can feel stressful)
- Not ideal for deep notes and personal knowledge
- Easy to confuse “stored” with “handled”
Data point and credibility check
Inbox overload is a widely discussed productivity drain. If you want a broad view of how email volume and constant messaging affect modern work habits, a useful starting point is the reporting archive at The Guardian’s coverage of workplace productivity and digital overload, which regularly cites research and expert commentary.
Actionable tips
- Turn any email into a task by adding one line at the top: “Next action:” then file it into Action.
- Unsubscribe aggressively: keep only newsletters you truly read monthly.
- Batch process email 2–4 times a day instead of staying always-on.
Which second brain should you choose? Use this decision matrix
Pick the approach that matches your bottleneck:
- You forget tasks and drop balls: Task-manager command center
- You can’t find information you know you saved: Notes-app knowledge hub
- You hate screens and want focus: Paper-first notebook
- Your best ideas happen away from a keyboard: Voice-first capture
- You live in email and need minimal change: Email-as-second-brain
If you’re torn between two, combine them lightly: a task manager for next actions + a notes app for reference is a common “sweet spot.” Avoid combining more than two tools at first.
Implementation plan: set it up in 60 minutes (and keep it alive)
Step 1: Define what you will capture (10 minutes)
- Tasks you must do
- Decisions you must remember
- Reusable information (templates, procedures, checklists)
Step 2: Create a tiny structure (15 minutes)
Limit yourself to five categories/folders/labels. More structure feels organized but increases maintenance and reduces retrieval speed.
Step 3: Add two reviews (15 minutes)
- Daily: 5 minutes to choose today’s top outcomes
- Weekly: 15 minutes to close loops, migrate tasks, and archive noise
Step 4: Write your personal rules (20 minutes)
- “If it takes under 2 minutes, I do it now.”
- “If it’s a commitment, it becomes a task with a next action.”
- “If I store it, I must be able to retrieve it within 30 seconds.”
Common mistakes to avoid (regardless of tool)
- Capturing without processing: unprocessed notes create guilt, not clarity.
- Over-tagging: tags are not a substitute for review.
- Too many inboxes: limit capture points (one notebook, one app, one email flow).
- No decision log: many repeated debates come from not documenting the “why.”
- Using due dates for everything: it trains you to ignore reminders.
Conclusion: the best second brain is the one you review
Second brain systems don’t succeed because they’re sophisticated—they succeed because they’re consistently maintained. If you want the highest odds of follow-through, choose one primary tool based on your biggest bottleneck, keep the structure minimal, and protect a daily and weekly review.
Whether you pick paper, a notes app, a task manager, voice capture, or email, aim for a system that makes it easier to act on what you know. That’s the real promise of a second brain: fewer repeated mistakes, faster decisions, and calmer execution.
Lakehouse vs Warehouse vs Data Mesh for Survey & Feedback Data: What Actually Works in 2026?
Why survey data is a special kind of “data services” headache
Survey and feedback data looks simple until you’re responsible for it. One day it’s a quick NPS form. The next day you’re juggling multi-language CSAT, product feedback text blobs, call center transcripts, and “why did you cancel?” responses across five tools—while your stakeholders still want a single dashboard that answers, “What’s driving churn this month?”
Compared to transactional data (orders, clicks, payments), surveys have quirks that change the “best” architecture:
- Messy schemas: every new survey version creates new columns, options, and question IDs.
- Small-to-medium volume, high context: the number of responses might be manageable, but the insights depend on metadata (audience segment, channel, language, timing).
- Text-heavy: open-ended answers push you toward document storage, search, and NLP pipelines.
- Privacy & governance: responses can contain sensitive personal data—even when you didn’t ask for it.
So, what’s the best “data services” approach for survey and feedback data in 2026? Let’s compare three popular options—data warehouse, lakehouse, and data mesh—with real-world patterns and actionable tips.
The contenders: warehouse, lakehouse, and data mesh (in plain English)
1) The classic Data Warehouse approach
A data warehouse (think Snowflake, BigQuery, Redshift) is the “clean, modeled, analytics-ready” path. You ingest survey data, standardize it into tables (facts/dimensions), and run SQL + BI.
Best for: consistent reporting, executive dashboards, and teams that value governed metrics over experimentation.
2) The Lakehouse approach
A lakehouse blends data lake storage (cheap files like Parquet/Delta/Iceberg on object storage) with warehouse-like features (ACID tables, SQL, governance). It’s popular when you want one place for structured survey results and semi-structured text, transcripts, or embeddings.
Best for: analytics + ML/NLP on feedback text, with flexibility to keep raw and curated data side by side.
3) The Data Mesh approach
Data mesh is more organizational than technical: survey data becomes a “product” owned by a domain team (e.g., Customer Experience or Product Research). They publish standardized, discoverable datasets with clear SLAs, quality checks, and definitions—so other teams can self-serve without endless central bottlenecks.
Best for: large orgs with multiple survey sources and repeated fights over definitions (NPS, “active user,” churn reasons, etc.).
Comparison: what matters for survey & feedback pipelines
Schema drift and survey versioning
Warehouse: Great if you enforce strict modeling—but survey versioning will constantly break assumptions. If question IDs change or answer options are updated, you’ll need robust dimension tables and mapping logic (and someone who loves data modeling).
Lakehouse: Handles schema drift more gracefully because you can store raw JSON events and later “promote” stable fields to curated tables. This is handy when you’re running experiments and changing survey wording weekly.
Data mesh: Solves the human problem: the owning team publishes a versioned “survey responses” product with explicit contracts (e.g., question_id is stable; question_text can change; options are tracked in a lookup table). Still needs tech underneath, but avoids chaos.
Tip: Regardless of architecture, store these fields for every response: survey_id, survey_version, question_id, question_type, language, channel, timestamp, and a respondent key (hashed if needed). Those six-ish fields are the difference between a usable dataset and a graveyard.
Open-ended responses (text) and “the AI question”
Open text answers are often where the value is (“I canceled because…”)—but they’re tough to operationalize.
Warehouse: You can store text in a column, but analytics often stops at keyword filtering. Some warehouses support search and ML features, but you’ll still feel friction when you try to do topic modeling, sentiment, or embeddings at scale.
Lakehouse: Typically the easiest place to run NLP pipelines because you can keep raw text, intermediate outputs (language detection, PII flags), and derived artifacts (topics, embeddings) in the same ecosystem. If you’re building a “voice of customer” engine, lakehouse usually wins.
Data mesh: Mesh shines when different teams need different “views” of text: Product wants feature requests; Support wants ticket deflection themes; Compliance wants sensitive data alerts. With mesh, each domain can publish tailored datasets while reusing shared standards.
Actionable example: Create a lightweight pipeline that generates three extra fields for every open-text answer:
- language_code (for routing and translation decisions)
- pii_risk_score (so analysts don’t accidentally expose personal details)
- topic_label (even if it’s a simple rule-based classifier to start)
This tiny step makes dashboards dramatically more useful—without waiting for a “full AI initiative.”
Governance, privacy, and trust
Survey data can include personal stories, names, phone numbers, or medical details—often volunteered by respondents. That makes governance non-negotiable.
Warehouse: Strong access controls and mature governance tooling. Easy to create “gold” tables that exclude PII and are safe for broad access.
Lakehouse: Can be equally governed, but success depends on how disciplined your team is with permissions, catalogs, and table-level policies. The flexibility that makes lakehouse great can also make it easier to accidentally expose raw text.
Data mesh: Encourages ownership: the domain team is accountable for privacy-safe outputs, documentation, and quality checks. Mesh is great when central data teams can’t realistically police every dataset.
Practical governance tip: Treat raw open-text as “restricted,” and create a redacted_text or safe_text_excerpt field for wider use. Even basic redaction (emails, phone numbers) reduces risk a lot.
Also, keep an eye on the broader public conversation around personal data and technology. For ongoing reporting and perspective, resources like The Guardian’s technology coverage can be a useful way to track real-world privacy concerns that eventually influence internal policy.
Speed to value vs long-term maintainability
Warehouse: Often fastest for “we need a dashboard by Friday.” Load data, model a few tables, connect BI, ship. Long-term maintainability is strong if you commit to modeling standards.
Lakehouse: Fast for exploration and iteration (especially with varied data types). Maintainability is great when you enforce a layered approach: raw → clean → curated → metrics.
Data mesh: Slower to start because it requires organizational alignment. But it pays off when survey data is used across many teams and definitions keep drifting.
Real-world scenarios: which approach wins?
Scenario A: “We’re a SaaS team with 2–3 survey sources and one BI tool”
If you’re pulling NPS from a survey tool, CSAT from your helpdesk, and maybe some in-app micro-surveys, a warehouse-first approach is usually enough.
What to do:
- Standardize a single response table shape (even if sources differ).
- Create consistent dimensions: customer, product area, channel, and time.
- Define 5–10 “blessed” metrics: response rate, NPS, top themes, detractor reasons.
Data point to watch: Response rates often drop when surveys get longer. If you see completion rate falling after question 5, that’s not just UX—it’s a data-quality issue that should influence analysis and sampling.
Scenario B: “We need AI-assisted theme detection from thousands of comments per week”
When open-text volume grows and stakeholders want automated categorization, lakehouse tends to win because it supports analytics + ML workflows without forcing everything into rigid relational modeling from day one.
What to do:
- Store raw responses as immutable records (append-only).
- Create a curated table with cleaned text (language normalization, stripping signatures).
- Generate topic labels weekly and track drift (topics change over time).
Actionable tip: Keep a “human override” table where researchers can correct topic labels. Use that as training/validation data later. It’s a simple practice that turns ad-hoc analysis into an improving system.
Scenario C: “Enterprise org with product, support, and research all running surveys (and arguing about ‘the truth’)”
This is where data mesh can be a lifesaver—especially if you’ve already tried centralizing everything and ended up with a backlog no one can escape.
What to do:
- Define domain-owned data products like “Customer Sentiment (Support)” and “Product Feedback (In-App).”
- Publish clear contracts: metric definitions, refresh cadence, and data quality checks.
- Create a shared “survey question registry” service so question IDs and meaning don’t fragment.
Concrete win: When each domain owns the meaning of its metrics, you reduce the classic meeting where ten people debate why NPS in one dashboard doesn’t match NPS in another.
A quick decision guide (no fluff)
- Choose a Warehouse if your priority is consistent reporting, you have a small number of survey sources, and you mainly need dashboards and SQL analytics.
- Choose a Lakehouse if open-text analytics, ML/NLP, and fast iteration matter—and you want to keep raw + curated data together.
- Choose Data Mesh if the bigger problem is organizational scale: many teams, many definitions, and constant confusion about “whose numbers are right.”
Implementation tips that work across all three approaches
1) Build a “question dimension” early
Create a table that tracks question_id, question_text, language, scale type (1–5, 0–10), and valid options. This prevents chaos when you rewrite questions or localize surveys.
2) Treat survey invites as first-class data
If you only store responses, your response rate metrics will be shaky. Track invites/deliveries too (even if it’s approximate). You’ll get more honest insight into bias (who answered vs who didn’t).
3) Put “explainability” into dashboards
For feedback analytics, stakeholders will distrust black-box charts. Add small notes like: “Topic labels are auto-generated weekly” or “NPS is calculated from the latest response per customer per quarter.” That reduces misinterpretation.
4) Set up a monthly “survey data quality” checklist
- Any new survey versions launched?
- Any spikes in ‘Other’ or blank answers?
- Any channel mix changes (email vs in-app) that could bias results?
- Any PII leakage detected in open-text?
This is low effort and catches issues before they show up as executive confusion.
Conclusion: the best architecture is the one that makes feedback usable
Survey data isn’t “big data,” but it’s high-stakes data—because it’s often the closest thing you have to direct customer truth. Warehouses are fantastic for consistent metrics and fast dashboards. Lakehouses are ideal when open-text and AI workflows become central. Data mesh is the organizational strategy that keeps definitions from collapsing under enterprise complexity.
If you’re building for Swift Survey-style workflows—where feedback needs to move from collection to insight to action—start with the pain you feel most (reporting consistency, text analytics, or cross-team trust). Then pick the approach that solves that pain without creating a new one.